BACK TO SELECTED WORK
CASE STUDY 05 / 09Studio / Automation
Headless document extraction pipeline
DocAgentLine
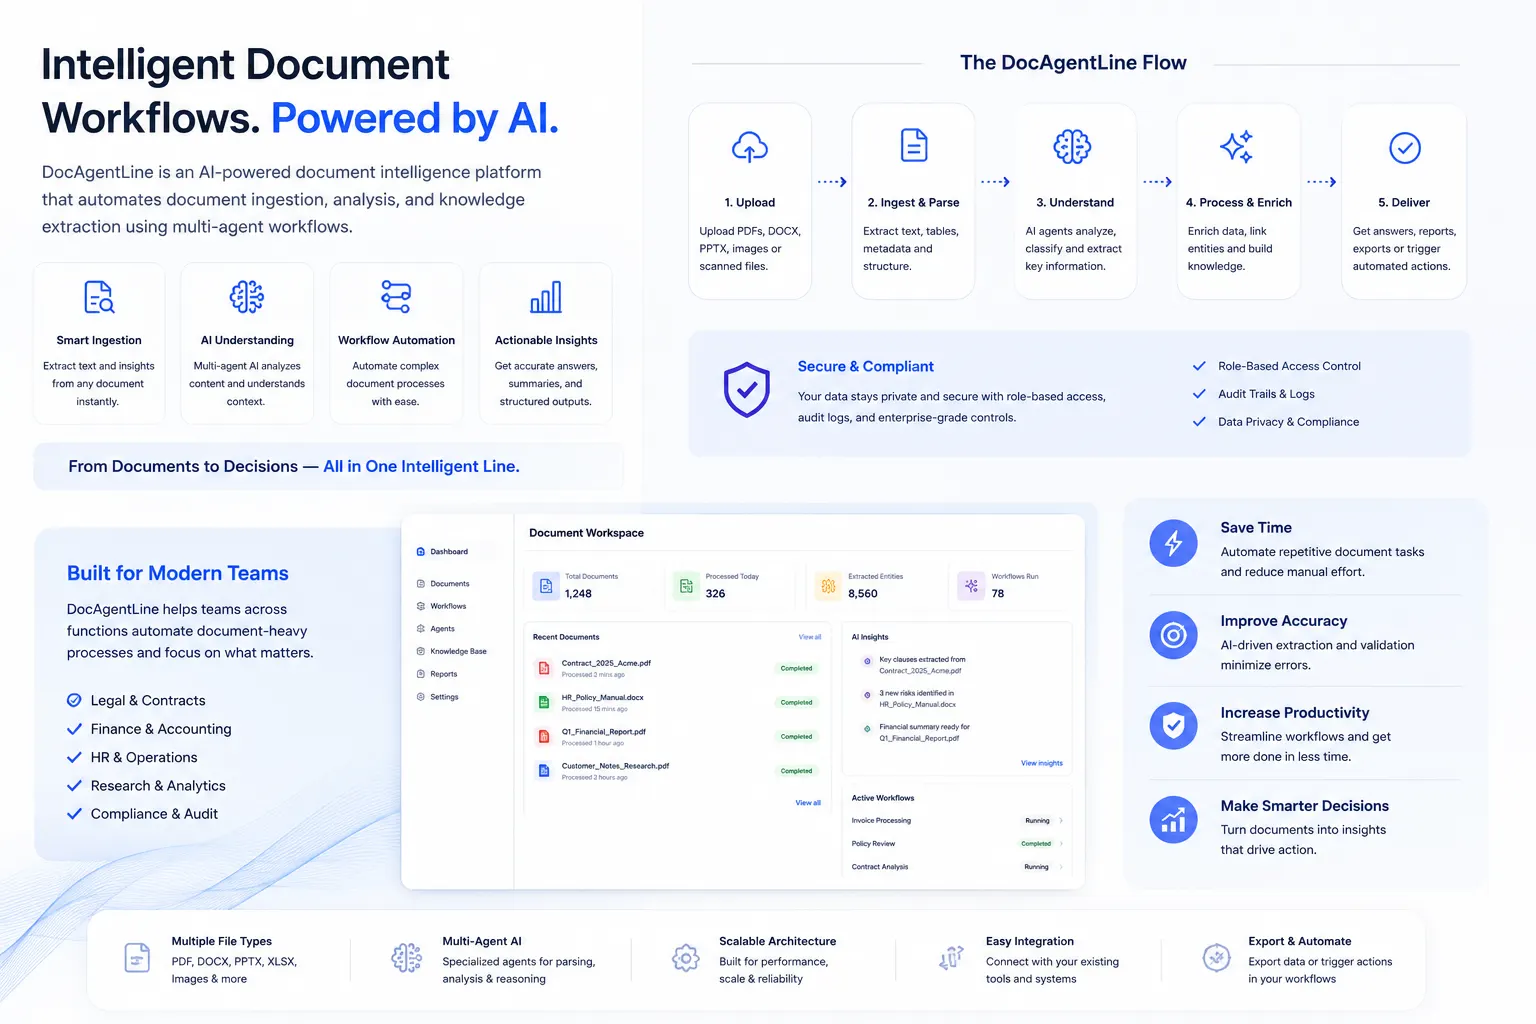
A production-grade automated document intelligence pipeline for ingesting files, extracting text and layout, chunking content, running LLM extraction, validating schemas, and preserving audit trails.
 PROJECT / STUDIO
01 / THE WORK
Behind the build.
DocAgentLine is built as a non-interactive pipeline for teams that need structured data from messy documents. It supports document ingestion through CLI or API, normalized extraction artifacts, schema-driven LLM outputs, validation, persistence, metrics, and auditable processing states.
02 / ENGINEERING DECISIONS
What makes it work.
01 / CAPABILITYHeadless CLI/API workflow for document submission and result retrieval
02 / CAPABILITYStructured extraction guided by schemas and validation rules
03 / CAPABILITYStage-oriented pipeline design with retry and resume concepts
04 / CAPABILITYArtifacts, metrics, state, and audit events persisted across runs
03 / INTERACTIVE WALKTHROUGH
From input to outcome.
STAGE 1 OF 5
Submit a document and schema version through CLI or API.
04 / ARCHITECTURE
Under the hood.
Unstructured Document Ingestion to Schema Validation Pipeline
Pipeline Diagram 5.1Step 1PDF / Image Intake
Step 2Layout Chunking
Step 3LLM Extraction
Step 4JSON Validation
Step 5Audit Storage
05 / RESULTS & USE CASES
Built to matter.
OUTCOME 01Reliable extraction from PDFs, images, text, and URLs
OUTCOME 02Traceable processing for compliance-sensitive workflows
OUTCOME 03Structured outputs that downstream systems can trust