Indus LLM Gateway
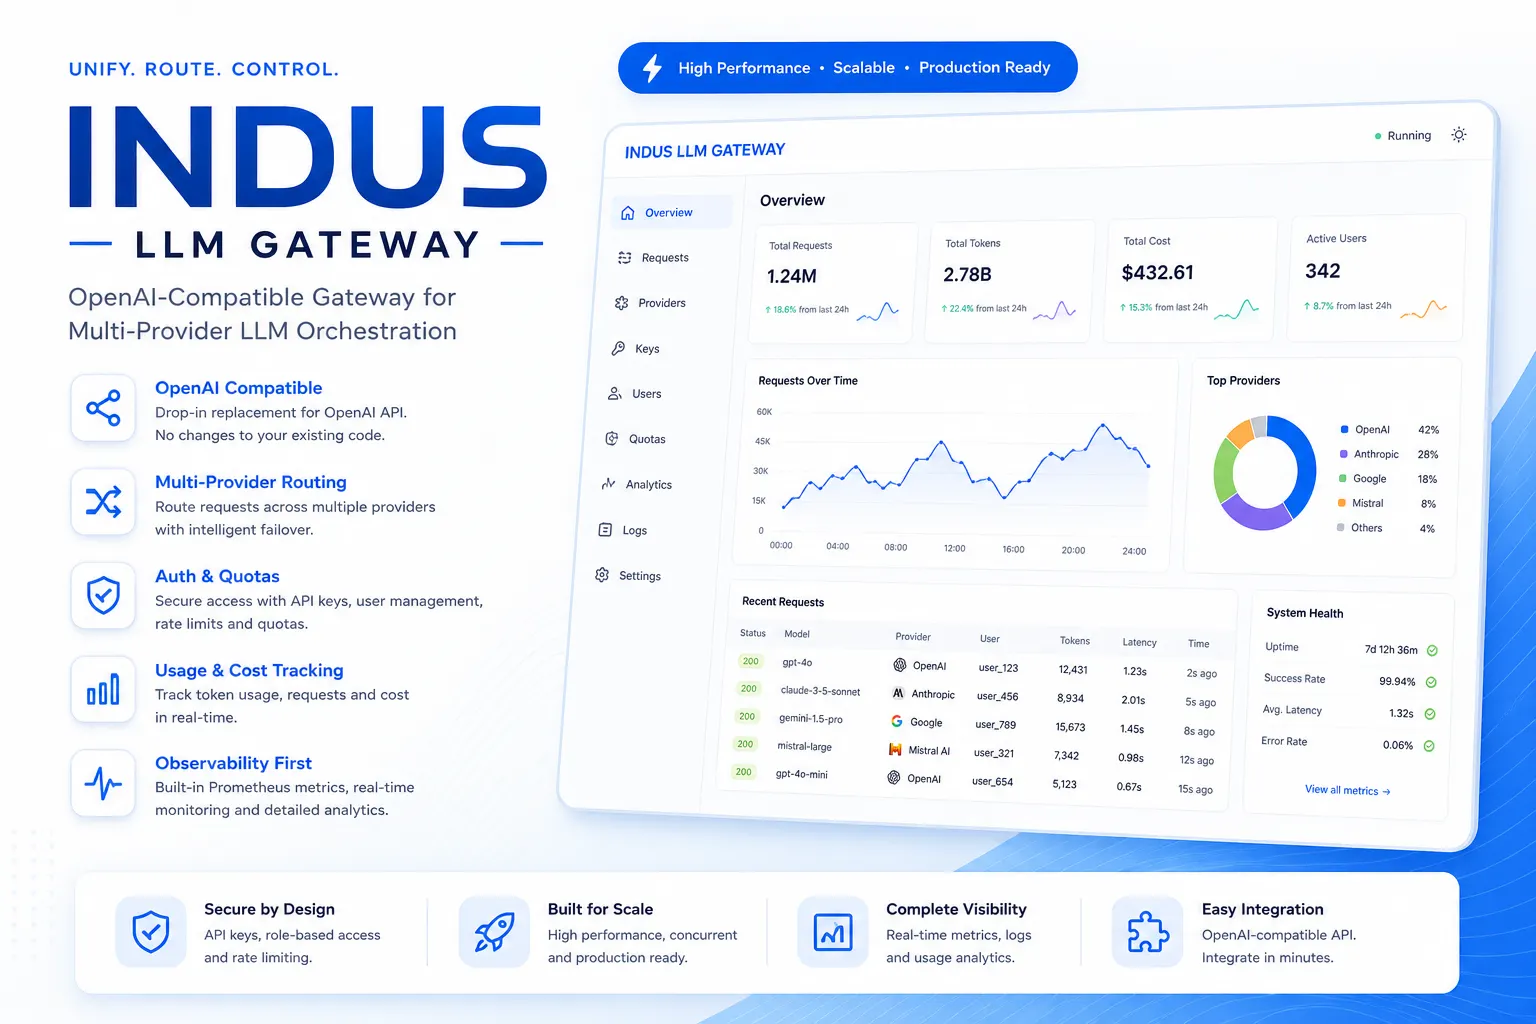
A production-ready, self-hosted LLM gateway that unifies provider routing, API authentication, quotas, memory, streaming, metrics, and dashboard visibility behind one OpenAI-compatible endpoint.
 PROJECT / CINEMATIC
Behind the build.
Indus LLM Gateway is built for teams that want one controlled entry point for AI traffic without rewriting their application code. It acts as a reverse proxy for OpenAI-compatible APIs, routes requests across providers and models, enforces API-key budgets, proxies streaming responses, injects prompt templates, tracks cost, and exposes Prometheus metrics plus an embedded web dashboard.
What makes it work.
From input to outcome.
Applications send standard chat completion requests to the gateway.
Under the hood.
Reverse Proxy Topology & Governance Loop
Architecture Diagram 2.1Standard `/v1/chat/completions` REST/SSE requests sent to Gateway endpoint.
Bearer token validation, rate limiters, token accounting, and budget enforcement.
Dynamic model dispatcher across OpenAI, Anthropic, Gemini, or local models.
Cost estimation, latency histograms, token usage, and live dashboard graphs.